面對每日一億筆(尖峰每秒破萬筆)的海量時序日誌 (Time Series Logs),傳統依賴關聯式資料庫 (SQL) 或手動按日建立索引(Time-based Index)的做法,往往會面臨寫入吞吐瓶頸、過度分片 (Over-sharding) 以及維運刪除繁瑣等問題。本文將從 SQL 與 Elasticsearch 的概念差異出發,透過 Docker 快速建立測試環境,並深入介紹如何利用 Data Stream 搭配索引生命週期管理 (ILM) 解決每日 Log 的寫入與自動輪轉問題,最後透過 ASP.NET Core 10 Web API 搭配基於 System.Threading.Channels 封裝的記憶體佇列類別 LogQueue 與背景消費者 LogBatchProcessor 實現高效能的非阻塞批次寫入與自動化測試。
開發環境
- Windows 11 / Ubuntu 24.04
- .NET 10.0 (C# 14)
- Elasticsearch 8.17.0
- Docker / Docker Compose
- Elastic.Clients.Elasticsearch 8.17.0
1. 核心概念:SQL vs Elasticsearch
1.1 名詞概念與適用時機
這裡先將大家熟悉的關聯式資料庫 (RDBMS / SQL) 與 Elasticsearch (ES) 做個名詞對照,方便快速建立心智模型:
| 關聯式資料庫 (SQL) | Elasticsearch (ES) | 說明 |
|---|---|---|
| Database | (Cluster 管理) | ES 叢集 (Cluster) 內負責統一管理多個 Index |
| Table | Index (索引) | 存放相同邏輯結構的文件集合 |
| Schema | Mapping (映射) | 定義欄位名稱與型別(如 text、keyword、date 等) |
| Row | Document (文件) | 一筆獨立的資料,以 JSON 格式儲存 |
| Column | Field (欄位) | JSON 物件中的 Key-Value 鍵值對 |
| Primary Key | **_id** | 每筆 Document 在 Index 內的唯一識別碼 |
| SQL Query | Query DSL | 基於 JSON 的查詢語法或 RESTful API |
至於選型時機:
- 使用 SQL:需要強 ACID 交易保證(例如金流轉帳)、頻繁跨表 JOIN 與嚴格外鍵約束的業務情境。
- 使用 ES:需要全文檢索、模糊搜尋,或是面對每日一億筆海量時序日誌 (Logs/Metrics) 的高速寫入與即時統計分析。
1.2 底層檢索差異:B+ Tree vs 倒排索引 (Inverted Index)
為什麼 Elasticsearch 搜尋全文速度遠遠快於傳統關聯式資料庫?關鍵在於底層的資料組織與檢索機制不同:
- SQL (正向儲存 / B+ Tree):資料以「列 (Row)」為核心儲存。若要搜尋
LIKE '%關鍵字%',因為無法有效利用 B+ Tree 前綴索引,必須逐筆全表掃描 (Full Table Scan),資料量一旦達到數百萬筆以上,效能就會急遽下滑。 - ES (倒排索引 / Inverted Index):在資料寫入時,Elasticsearch 會先將文字進行分詞 (Tokenize),建立一份「詞彙指向文件 ID 清單」的字典。查詢時直接查字典,毫秒級就能取得匹配清單,完全不需要掃描全表。
這裡我們用對比清楚解析兩者的搜尋機制差異:
1. 傳統 SQL 正向儲存 (Row-based) 檢索方式
資料表儲存結構:
| 資料列 (Row ID) | 內文 (Title / Message) |
|---|---|
| Doc 1 | Elasticsearch 實戰指南 |
| Doc 2 | ASP.NET Core 10 開發筆記 |
| Doc 3 | Elasticsearch 效能調校 |
搜尋流程 (LIKE '%Elasticsearch%'):
- [掃描 Doc 1 (命中)] ➔ [掃描 Doc 2 (不符)] ➔ [掃描 Doc 3 (命中)]
- ⚠️ 問題:無法有效利用 B+ Tree 前綴索引,必須逐筆全表掃描 (Full Table Scan),資料量越大耗時越長!
2. Elasticsearch 倒排索引 (Inverted Index) 檢索方式
【寫入時分詞建立字典】
- 文件寫入 ➔ 分詞器 (Tokenizer) 拆解單字 ➔ 建立詞彙字典與倒排清單 (Posting List)
【倒排清單結構 (Posting List)】
| Term (詞彙) | 包含該詞的 Document ID 清單 (帶有詞頻與位置資訊) | 命中說明 |
|---|---|---|
| ASP.NET | [ Doc 2 ] | |
| Core | [ Doc 2 ] | |
| Elasticsearch | [ Doc 1, Doc 3 ] | 👉 命中!直接取得 Doc 1 與 Doc 3 |
| 調校 | [ Doc 3 ] | |
| 實戰 | [ Doc 1 ] |
搜尋流程 (Elasticsearch):
- 輸入查詢詞 ➔ 直接查找 Term Dictionary ➔ 立即返回 [Doc 1, Doc 3](時間複雜度接近 $O(1) \sim O(\log N)$)
- ✨ 優勢:無需全表逐筆掃描,即使每日一億筆資料依然具備毫秒級查詢效能!
2. 環境準備:Docker Compose 快速啟動
這裡我們建立一個單節點 (Single-node) 的 Elasticsearch 8.17 測試環境。
docker-compose.yml 設定如下:
services:
  elasticsearch:
    image: docker.elastic.co/elasticsearch/elasticsearch:8.17.0
    container_name: es-lab
    environment:
      - discovery.type=single-node
      - xpack.security.enabled=false # 本機測試關閉驗證,正式環境請務必開啟
      - "ES_JAVA_OPTS=-Xms512m -Xmx512m"
    ports:
      - "9200:9200"
    healthcheck:
      test: ["CMD-SHELL", "curl -s http://localhost:9200/_cluster/health | grep -q '\"status\":\"green\"\\|\"status\":\"yellow\"'"]
      interval: 5s
      timeout: 5s
      retries: 20
執行以下指令啟動容器:
docker compose up -d
3. 快速上手:手把手實操與終端機真實執行畫面
接下來透過 curl 實際演練最基礎的 CRUD 操作。
步驟 1:建立 Index(相當於 CREATE TABLE)
透過 HTTP PUT 建立名為 my-first-index 的索引並定義 Mapping:
curl -X PUT "http://localhost:9200/my-first-index" \
  -H "Content-Type: application/json" \
  -d '{
    "settings": {
      "number_of_shards": 1,
      "number_of_replicas": 0
    },
    "mappings": {
      "properties": {
        "title": { "type": "text" },
        "category": { "type": "keyword" },
        "price": { "type": "double" },
        "createdAt": { "type": "date" }
      }
    }
  }'
終端機回應畫面如下:
{
  "acknowledged": true,
  "shards_acknowledged": true,
  "index": "my-first-index"
}
步驟 2:建立 Document(相當於 INSERT INTO)
方式 A:指定 Document ID 寫入(PUT /<index>/_doc/<id>)
以自訂 ID doc-001 寫入一筆文件:
curl -X PUT "http://localhost:9200/my-first-index/_doc/doc-001" \
  -H "Content-Type: application/json" \
  -d '{
    "title": "Elasticsearch 實戰指南",
    "category": "Book",
    "price": 580.0,
    "createdAt": "2026-08-23T16:50:00Z"
  }'
終端機回應畫面如下:
{
  "_index": "my-first-index",
  "_id": "doc-001",
  "_version": 1,
  "result": "created",
  "_shards": {
    "total": 1,
    "successful": 1,
    "failed": 0
  },
  "_seq_no": 0,
  "_primary_term": 1
}
方式 B:自動產生 Document ID 寫入(POST /<index>/_doc,高吞吐量推薦)
使用 POST 讓 Elasticsearch 自動生成唯一 ID:
curl -X POST "http://localhost:9200/my-first-index/_doc" \
  -H "Content-Type: application/json" \
  -d '{
    "title": "ASP.NET Core 10 開發筆記",
    "category": "Book",
    "price": 620.0,
    "createdAt": "2026-08-23T16:50:00Z"
  }'
終端機回應畫面如下:
{
  "_index": "my-first-index",
  "_id": "LK7PLaABbPQ5FnXdYYdS",
  "_version": 1,
  "result": "created",
  "_shards": {
    "total": 1,
    "successful": 1,
    "failed": 0
  },
  "_seq_no": 1,
  "_primary_term": 1
}
NOTE: 在每日一億筆高吞吐場景下,務必採用「自動產生 ID」的方式寫入。自訂 ID 會讓 ES 額外做版本檢查與隨機讀取,降低寫入效能。
步驟 3:查詢 Document(相當於 SELECT)
方式 A:依 ID 查詢單筆
透過指定 Document ID 直接取得資料:
curl "http://localhost:9200/my-first-index/_doc/doc-001"
終端機回應畫面如下:
{
  "_index": "my-first-index",
  "_id": "doc-001",
  "_version": 1,
  "_seq_no": 0,
  "_primary_term": 1,
  "found": true,
  "_source": {
    "title": "Elasticsearch 實戰指南",
    "category": "Book",
    "price": 580.0,
    "createdAt": "2026-08-23T16:50:00Z"
  }
}
方式 B:全文檢索搜尋
透過 _search 端點進行 match 關鍵字搜尋:
curl -X POST "http://localhost:9200/my-first-index/_search" \
  -H "Content-Type: application/json" \
  -d '{
    "query": {
      "match": {
        "title": "Elasticsearch"
      }
    }
  }'
終端機回應畫面如下:
{
  "took": 2,
  "timed_out": false,
  "_shards": {
    "total": 1,
    "successful": 1,
    "skipped": 0,
    "failed": 0
  },
  "hits": {
    "total": {
      "value": 1,
      "relation": "eq"
    },
    "max_score": 0.8754687,
    "hits": [
      {
        "_index": "my-first-index",
        "_id": "doc-001",
        "_score": 0.8754687,
        "_source": {
          "title": "Elasticsearch 實戰指南",
          "category": "Book",
          "price": 580.0,
          "createdAt": "2026-08-23T16:50:00Z"
        }
      }
    ]
  }
}
4. 架構設計:每日一億筆時序資料(Data Stream + ILM)
面對每日一億筆(平均每秒千筆、尖峰每秒破萬筆)的高吞吐時序資料,架構設計有兩大核心原則:
- 一律自動產生 Document ID:避免自訂 ID 觸發 Version Check 產生隨機磁碟讀取;自動產生 ID 是純 Append 寫入,效能可提升 30%~50%。
- 採用 Data Stream + ILM 架構:免去手動維護每日索引名稱與外部排程刪除的負擔。
4.1 關鍵觀念:Index 根據欄位建立後,每日 Log Doc 還要額外指定?
在設計時序日誌 (Time Series Logs) 時,常有朋友詢問:「既然 Index 已經事先定義好了欄位 Mapping,那每天寫入 Log 時,應用程式端到底要不要在程式碼中指定當天日期?」
這裡把前因後果與現代解決方案做個深入說明。
1. 前因:傳統手動按日建索引(Time-based Index)的痛點
早期(ES 7 以前)常見的做法是由應用程式在傳送請求時,動態組裝當天的日期作為索引名稱(例如 logs-2026.08.23):
- 程式碼維護繁瑣:應用程式端必須在每次寫入時計算
$"logs-{DateTime.UtcNow:yyyy.MM.dd}",若遇到時區轉換、跨日臨界點或延遲到達的 Log,容易發生寫錯索引或產生分散碎索引的問題。 - 分片大小極度不均勻(Over-sharding):
- 業務離峰日(如週末或連假)Log 量少,但依然會建立出完整的 Shard,產生大量 < 1GB 的小分片,白白浪費 Elasticsearch Node 的 JVM Heap 記憶體。
- 業務尖峰日(如大型促銷活動)Log 量暴增,單日索引可能膨脹至數百 GB,導致單一 Shard 過大、查詢與復原變慢。
- 過期清理需要額外維運:必須在外部另外撰寫 CronJob 腳本(或使用 Curator 工具),每天定時掃描並下指令刪除 30 天前的舊索引名稱。
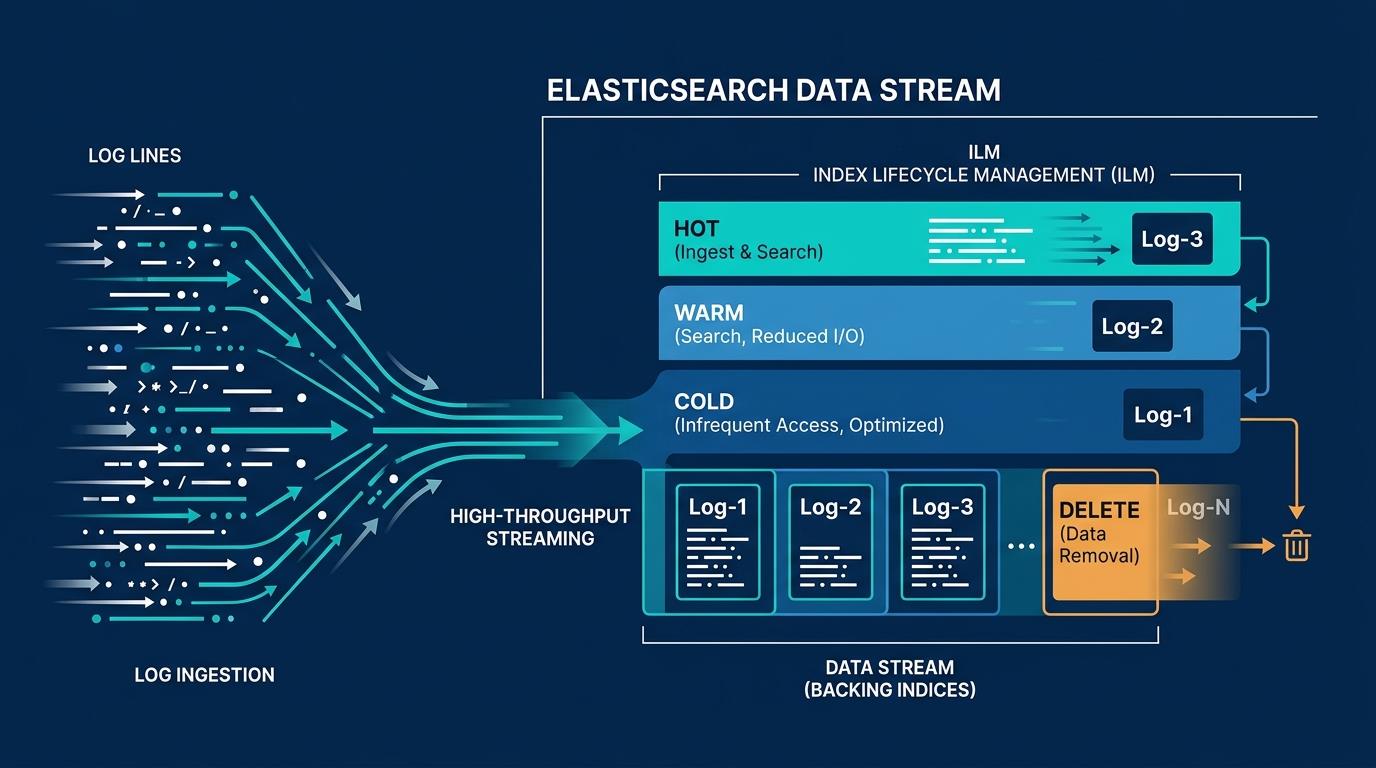
2. 後果與解法:現代 Data Stream + ILM 架構
Elasticsearch 官方推出 Data Stream 就是為了解決上述痛點:
- 寫入端點永遠固定:應用程式的寫入目標永遠是同一個抽象名稱(如
POST /logs-app-prod/_bulk),程式碼中完全不需要任何計算日期或字串組裝邏輯。 - 分片容量自動最佳化:由 ILM(Index Lifecycle Management,索引生命週期管理)在底層全自動監控。當底層當前索引累積滿 40 GB(或滿 1 天)時,ES 會自動執行 Rollover 產生下一個 Backing Index(例如
.ds-logs-app-prod-2026.08.23-000001),確保每個 Shard 都維持在最佳效能尺寸(10~50GB)。 - 生命週期自動清理:ILM 內建自動過期機制,滿 30 天的資料會自動在底層被安全刪除,完全不需要維運人員手動清理。
3. 傳統做法 vs 現代 Data Stream 做法完整對照表
| 比較項目 | 傳統做法(手動按日建索引) | 現代推薦做法(Data Stream + ILM) |
|---|---|---|
| 寫入目標端點 | 每天動態變化:POST /logs-2026.08.23/_doc | 永遠固定不變:POST /logs-app-prod/_bulk |
| 程式端是否需算日期 | 要(需寫 $"logs-{DateTime.UtcNow:yyyy.MM.dd}") | 完全不用(永遠指向固定 Data Stream) |
| Document 資料需求 | 純 JSON 欄位 | JSON 欄位中必須包含 @timestamp |
| 分片(Shard)均勻度 | 差(量少時 Shard 過小浪費記憶體,暴量時 Shard 過大) | 優(由 ILM 嚴格依照「每滿 40GB」自動 Rollover 切分) |
| 生命週期自動清理 | 需額外寫外部 CronJob / 腳本定期掃描刪除 | 內建自動化(由 ILM 策略設定滿 30 天底層自動刪除) |
4. Document 資料需求與寫入規範
- 欄位結構(Mapping)已事先固化:
- 在 Index Template 中已經定義了
service (keyword)、message (text)、level (keyword)等型別,寫入 Document 時不需要在 Header 或 Body 重複宣告結構。 - 必備
@timestamp欄位: - 寫入 Document 時,只要在 JSON 本體包含
@timestamp(ISO 8601 UTC 時間字串,例如"2026-08-23T17:30:00.000Z"),Elasticsearch 就會依據該時間戳記,在底層自動分流到當前啟用的 Backing Index 中。
5. 程式碼直觀對比:傳統 C# 寫法 vs Data Stream C# 寫法
這裡我們直接看兩者在應用程式端的寫法差異:
🔴 傳統手動按日索引寫法(Time-based Index):
// 1. 寫入:每次寫入都必須手動計算與拼接當天日期字串(有跨日時區計算風險)
var dailyIndex = $"logs-app-{DateTime.UtcNow:yyyy.MM.dd}";
await _client.IndexAsync(entry, idx => idx.Index(dailyIndex));

// 2. 查詢:跨日搜尋時,必須手動計算日期區間並組出多個索引清單
var targetIndices = new[] { "logs-app-2026.08.22", "logs-app-2026.08.23" };
var response = await _client.SearchAsync<LogEntry>(s => s
    .Indices(targetIndices.Select(x => (IndexName)x).ToArray())
    .Query(...)
);
🟢 現代 Data Stream 寫法(推薦):
// 1. 寫入:目標端點永遠固定,程式碼零日期組裝邏輯(由 ES 底層 ILM 依容量與天數自動切分)
await _client.BulkAsync(b => b
    .Index("logs-app-prod")
    .CreateMany(logs)
);

// 2. 查詢:直接指向固定 Data Stream,ES 底層自動跨 Backing Indices 平行檢索
var response = await _client.SearchAsync<LogEntry>(s => s
    .Indices("logs-app-prod")
    .Query(...)
);
4.2 初始化 ILM 與 Data Stream 腳本
這裡我們設定 ILM 策略(滿 40GB 或滿 1 天自動 Rollover,30 天後自動刪除),並建立 Index Template 綁定 Data Stream:
# 1. 建立 ILM 策略 (滿 40GB 或 1 天 Rollover,30 天後刪除)
curl -X PUT "http://localhost:9200/_ilm/policy/logs_ilm_policy" \
  -H "Content-Type: application/json" \
  -d '{
    "policy": {
      "phases": {
        "hot": {
          "actions": {
            "rollover": {
              "max_primary_shard_size": "40gb",
              "max_age": "1d"
            }
          }
        },
        "delete": {
          "min_age": "30d",
          "actions": {
            "delete": {}
          }
        }
      }
    }
  }'

# 2. 建立 Index Template 綁定 Data Stream
curl -X PUT "http://localhost:9200/_index_template/logs_template" \
  -H "Content-Type: application/json" \
  -d '{
    "index_patterns": ["logs-app-*"],
    "data_stream": { },
    "template": {
      "settings": {
        "index.lifecycle.name": "logs_ilm_policy",
        "index.number_of_shards": 2,
        "index.number_of_replicas": 1,
        "index.refresh_interval": "10s"
      },
      "mappings": {
        "properties": {
          "@timestamp": { "type": "date" },
          "service": { "type": "keyword" },
          "level": { "type": "keyword" },
          "message": { "type": "text" },
          "traceId": { "type": "keyword" }
        }
      }
    },
    "priority": 500
  }'
5. ASP.NET Core 10 Web API 實作
專案完整原始碼位於 src/EsDailyLogsApi。使用官方 8.x SDK 套件:
dotnet add package Elastic.Clients.Elasticsearch --version 8.17.0
5.1 核心類別設計與架構
面對每日一億筆高併發寫入,API 不能每次收到請求就同步呼叫 ES,否則容易造成連線池耗盡與 HTTP 逾時。這裡我們拆分成以下幾個核心類別 (Class):
- 資料模型類別 (
LogEntry.cs):
定義 Log 結構,透過[JsonPropertyName("@timestamp")]映射 ES 時序必備欄位。 - 記憶體非阻塞佇列類別 (
LogQueue.cs/ILogQueue):
封裝 .NET 內建的System.Threading.Channels.Channel<LogEntry>作為高吞吐記憶體佇列 (Queue),寫入操作不阻塞,耗時 < 1ms。 - 背景批次寫入類別 (
LogBatchProcessor.cs):
繼承BackgroundService,作為 Queue 的背景消費者 (Consumer),從ILogQueue批次取出 Log(如每 100~500 筆或每 500ms),透過ElasticsearchClient.BulkAsync批次寫入固定的 Data Stream 端點(logs-app-prod)。 - Data Stream 查詢與維運服務類別 (
LogService.cs/ILogService):
封裝ElasticsearchClient,提供單筆查詢、時序區間全文檢索,以及針對底層 Backing Index 的更新與刪除操作。 - 手動按日索引服務類別 (
DailyIndexLogService.cs/IDailyIndexLogService):
作為對照組,示範 Time-based 手動組裝$"logs-app-{yyyy.MM.dd}"寫入與手動計算日期區間跨多索引搜尋的寫法。
5.2 記憶體佇列實作 (LogQueue.cs)
這裡透過 Channel.CreateBounded<LogEntry> 建立有界佇列,提供非阻塞的入隊 (EnqueueAsync) 與非同步串流讀取 (ReadAllAsync):
public interface ILogQueue
{
    ValueTask EnqueueAsync(LogEntry entry, CancellationToken ct = default);
    IAsyncEnumerable<LogEntry> ReadAllAsync(CancellationToken ct = default);
}

public class LogQueue : ILogQueue
{
    private readonly Channel<LogEntry> _channel;

    public LogQueue()
    {
        var options = new BoundedChannelOptions(500_000)
        {
            FullMode = BoundedChannelFullMode.Wait
        };
        _channel = Channel.CreateBounded<LogEntry>(options);
    }

    public ValueTask EnqueueAsync(LogEntry entry, CancellationToken ct = default)
        => _channel.Writer.WriteAsync(entry, ct);

    public IAsyncEnumerable<LogEntry> ReadAllAsync(CancellationToken ct = default)
        => _channel.Reader.ReadAllAsync(ct);
}
NOTE: 這裡的記憶體佇列
LogQueue在真實生產環境或跨節點分散式架構下,完全有機會換成外部的 Message Queue(例如 Kafka、RabbitMQ、AWS SQS 等);不過為了演練與本機快速展示,這裡就先使用 .NET 內建的記憶體 Queue 來實作。透過定義抽象介面ILogQueue,日後若要抽換成外部 Message Queue 也非常容易。
5.3 背景批次處理器實作 (LogBatchProcessor.cs)
這裡的 LogBatchProcessor 類別會在背景持續監聽 ILogQueue,累積滿批次量或時間到達時呼叫 BulkAsync 批次寫入:
public class LogBatchProcessor : BackgroundService
{
    private readonly ILogQueue _queue;
    private readonly ElasticsearchClient _client;
    private readonly ILogger<LogBatchProcessor> _logger;

    private const int BatchSize = 100;
    private static readonly TimeSpan FlushInterval = TimeSpan.FromMilliseconds(500);
    public const string TargetDataStream = "logs-app-prod";

    public LogBatchProcessor(
        ILogQueue queue,
        ElasticsearchClient client,
        ILogger<LogBatchProcessor> logger)
    {
        _queue = queue;
        _client = client;
        _logger = logger;
    }

    protected override async Task ExecuteAsync(CancellationToken stoppingToken)
    {
        var buffer = new List<LogEntry>(BatchSize);
        var lastFlushTime = DateTime.UtcNow;

        while (!stoppingToken.IsCancellationRequested)
        {
            try
            {
                await foreach (var item in _queue.ReadAllAsync(stoppingToken))
                {
                    buffer.Add(item);

                    bool isOverdue = DateTime.UtcNow - lastFlushTime >= FlushInterval;
                    if (buffer.Count >= BatchSize || isOverdue)
                    {
                        await _01_批次寫入Elasticsearch(buffer);
                        buffer.Clear();
                        lastFlushTime = DateTime.UtcNow;
                    }
                }
            }
            catch (OperationCanceledException) when (stoppingToken.IsCancellationRequested)
            {
                break;
            }
            catch (Exception ex)
            {
                _logger.LogError(ex, "批次處理過程發生未預期錯誤");
                await Task.Delay(500, stoppingToken);
            }
        }

        if (buffer.Count > 0)
        {
            await _01_批次寫入Elasticsearch(buffer);
        }
    }

    private async Task _01_批次寫入Elasticsearch(List<LogEntry> logs)
    {
        if (logs.Count == 0) return;

        var response = await _client.BulkAsync(b => b
            .Index(TargetDataStream)
            .CreateMany(logs)
        );

        if (!response.IsValidResponse)
        {
            _logger.LogError("Bulk 寫入失敗: {DebugInfo}", response.DebugInformation);
        }
    }
}
5.4 手動按日索引實作 (DailyIndexLogService.cs)
這裡展示手動按日索引做法:寫入時動態組裝 logs-app-yyyy.MM.dd,跨日查詢時手動列出所有日期的單日索引名稱:
public interface IDailyIndexLogService
{
    Task<bool> WriteLogAsync(LogEntry log);
    Task<IReadOnlyCollection<LogEntry>> QueryLogsAsync(string? service, string? keyword, DateTime from, DateTime to, int size = 50);
}

public class DailyIndexLogService : IDailyIndexLogService
{
    private readonly ElasticsearchClient _client;
    private readonly ILogger<DailyIndexLogService> _logger;

    public DailyIndexLogService(ElasticsearchClient client, ILogger<DailyIndexLogService> logger)
    {
        _client = client;
        _logger = logger;
    }

    public async Task<bool> WriteLogAsync(LogEntry log)
    {
        var dailyIndex = $"logs-app-{log.Timestamp:yyyy.MM.dd}";
        var response = await _client.IndexAsync(log, idx => idx.Index(dailyIndex));
        return response.IsValidResponse;
    }

    public async Task<IReadOnlyCollection<LogEntry>> QueryLogsAsync(
        string? service, string? keyword, DateTime from, DateTime to, int size = 50)
    {
        var targetIndices = new List<string>();
        for (var date = from.Date; date <= to.Date; date = date.AddDays(1))
        {
            targetIndices.Add($"logs-app-{date:yyyy.MM.dd}");
        }

        var filters = new List<Query>
        {
            new DateRangeQuery(new Field("@timestamp"))
            {
                Gte = from.ToString("o"),
                Lte = to.ToString("o")
            }
        };

        if (!string.IsNullOrWhiteSpace(service))
            filters.Add(new MatchQuery(Infer.Field<LogEntry>(f => f.Service)) { Query = service });

        var mustQueries = new List<Query>();
        if (!string.IsNullOrWhiteSpace(keyword))
            mustQueries.Add(new MatchQuery(Infer.Field<LogEntry>(f => f.Message)) { Query = keyword });

        var response = await _client.SearchAsync<LogEntry>(s => s
            .Indices(targetIndices.Select(x => (IndexName)x).ToArray())
            .Size(size)
            .Sort(sort => sort.Field(new Field("@timestamp"), new FieldSort { Order = SortOrder.Desc }))
            .Query(new BoolQuery
            {
                Filter = filters,
                Must = mustQueries.Count > 0 ? mustQueries : null
            })
        );

        return response.IsValidResponse ? response.Documents : Array.Empty<LogEntry>();
    }
}
5.5 Minimal API 依賴注入與端點註冊 (Program.cs)
在 Program.cs 註冊各個 Class 服務,包含現代 Data Stream 端點與手動單日索引端點:
var builder = WebApplication.CreateBuilder(args);

var settings = new ElasticsearchClientSettings(new Uri("http://localhost:9200"))
    .MaximumRetries(3)
    .RequestTimeout(TimeSpan.FromSeconds(30));

builder.Services.AddSingleton(new ElasticsearchClient(settings));
builder.Services.AddSingleton<ILogQueue, LogQueue>();
builder.Services.AddHostedService<LogBatchProcessor>();
builder.Services.AddScoped<ILogService, LogService>();
builder.Services.AddScoped<IDailyIndexLogService, DailyIndexLogService>();

var app = builder.Build();

// -------------------------------------------------------------
// [現代 Data Stream 模式]
// -------------------------------------------------------------

// [Create] 寫入 Log (推入 Queue 並回傳 202 Accepted,不需指定日期)
app.MapPost("/api/logs", async (LogEntry entry, ILogQueue queue) =>
{
    entry.Timestamp = DateTime.UtcNow;
    await queue.EnqueueAsync(entry);
    return Results.Accepted();
});

// [Read] 依 ID 取得單筆 Log
app.MapGet("/api/logs/{id}", async (string id, ILogService service) =>
{
    var log = await service.GetByIdAsync(id);
    return log != null ? Results.Ok(log) : Results.NotFound();
});

// [Read] 依條件搜尋 Logs (Data Stream)
app.MapGet("/api/logs", async (
    string? service, string? keyword, DateTime? from, DateTime? to, int? size,
    ILogService logService) =>
{
    var startTime = from ?? DateTime.UtcNow.AddHours(-24);
    var endTime = to ?? DateTime.UtcNow.AddMinutes(5);
    var pageSize = size ?? 50;

    var logs = await logService.QueryLogsAsync(service, keyword, startTime, endTime, pageSize);
    return Results.Ok(logs);
});

// [Update] 修改 Log 內容 (需指定底層 Backing Index)
app.MapPut("/api/logs/{index}/{id}", async (
    string index, string id, UpdateLogRequest req, ILogService logService) =>
{
    var success = await logService.UpdateLogMessageAsync(index, id, req.Message);
    return success ? Results.NoContent() : Results.BadRequest();
});

// [Delete] 刪除 Log (需指定底層 Backing Index)
app.MapDelete("/api/logs/{index}/{id}", async (
    string index, string id, ILogService logService) =>
{
    var success = await logService.DeleteLogAsync(index, id);
    return success ? Results.NoContent() : Results.NotFound();
});

// -------------------------------------------------------------
// [手動按日索引模式 (Daily Index)]
// -------------------------------------------------------------

// [Create] 手動按日寫入 Log
app.MapPost("/api/daily-index/logs", async (LogEntry entry, IDailyIndexLogService dailyIndexService) =>
{
    entry.Timestamp = DateTime.UtcNow;
    var success = await dailyIndexService.WriteLogAsync(entry);
    return success ? Results.Created($"/api/daily-index/logs/{entry.Id}", entry) : Results.BadRequest();
});

// [Read] 跨單日索引搜尋 Logs
app.MapGet("/api/daily-index/logs", async (
    string? service, string? keyword, DateTime? from, DateTime? to, int? size,
    IDailyIndexLogService dailyIndexService) =>
{
    var startTime = from ?? DateTime.UtcNow.AddHours(-24);
    var endTime = to ?? DateTime.UtcNow.AddMinutes(5);
    var pageSize = size ?? 50;

    var logs = await dailyIndexService.QueryLogsAsync(service, keyword, startTime, endTime, pageSize);
    return Results.Ok(logs);
});

app.Run();
6. 端對端驗證與自動化測試(BDD + Testcontainers)
為落實可靠的整合測試與規格化驗證,本專案採用 BDD(Reqnroll / Cucumber .NET) 搭配 Testcontainers for .NET 架構:
- Testcontainers 拋棄式容器隔離:在測試啟動時自動透過
Testcontainers.Elasticsearch啟動真實的 Elasticsearch 8.17.0 容器,測試完畢自動銷毀,不再依賴本機手動啟動的環境。 - BDD 規格化活文件 (Living Documentation):透過 Gherkin 語法與繁體中文撰寫完整的情境規格(Feature & Scenario)。
6.1 BDD 規格檔範例 (DataStreamLogs.feature)
這裡展示 Data Stream 完整生命週期的繁體中文 BDD 規格定義:
Feature: 現代 Data Stream 日誌管理
  作為系統維運與開發人員
  我想透過 API 將日誌寫入 Elasticsearch Data Stream 並進行查詢、更新與刪除
  以便高效管理海量日誌

  Background:
    Given Elasticsearch 服務已正常運作
    And 系統 API 服務已啟動

  Scenario: 透過 API 寫入日誌並經由背景批次處理器寫入 Data Stream
    Given 我有一筆日誌資料:
      | Service       | Level       | Message                    | TraceId       |
      | order-service | Information | 訂單建立成功,訂單編號 ORD-1001 | trace-bdd-001 |
    When 我發送 POST 請求至 "/api/logs" 寫入該日誌
    Then API 應回傳 HTTP 狀態碼 202
    And 等待背景批次處理器將日誌寫入 Data Stream
    Then 透過 Data Stream 全文檢索關鍵字 "ORD-1001" 應能查得該筆日誌

  Scenario: 透過 API 依 ID 查詢單筆日誌
    Given Data Stream 中已存在一筆日誌:
      | Service         | Level       | Message                   | TraceId       |
      | payment-service | Information | 信用卡授權扣款完成 NT$ 1500 | trace-bdd-002 |
    When 我發送 GET 請求依日誌 ID 查詢該筆日誌
    Then API 應回傳 HTTP 狀態碼 200
    And 回傳的日誌內容訊息應為 "信用卡授權扣款完成 NT$ 1500"
6.2 執行自動化測試專案
測試專案位於 tests/EsDailyLogsApi.Tests,包含:
- BDD 規格測試:
DataStreamLogs.feature:驗證 Data Stream 寫入、全文檢索、單筆查詢、更新與刪除。DailyIndexLogs.feature:驗證手動按日索引模式(/api/daily-index/logs)的寫入與跨日範圍查詢。- 單元與整合測試:
LogQueueTests.cs:驗證System.Threading.Channels的非阻塞寫入與讀取。LogServiceIntegrationTests.cs:對 ES 執行 Data Stream 下完整的 CRUD 生命週期驗證。DailyIndexLogServiceIntegrationTests.cs:驗證手動單日索引的寫入與範圍檢索。LogApiIntegrationTests.cs:Web API 端點整合測試。
執行測試指令:
dotnet test EsDailyLogs.slnx
終端機測試執行通過畫面如下(11 個測試 100% 通過):
Test run for tests/EsDailyLogsApi.Tests/bin/Debug/net10.0/EsDailyLogsApi.Tests.dll (.NETCoreApp,Version=v10.0)
Starting test execution, please wait...
A total of 1 test files matched the specified pattern.

Passed!  - Failed:     0, Passed:    11, Skipped:     0, Total:    11, Duration: 26 s
6.2 執行 Bash 模擬腳本
專案中也提供了 test_api.sh 腳本,模擬真實 API 呼叫:
啟動 Web API 與執行測試腳本:
# 1. 啟動 Web API
dotnet run --project src/EsDailyLogsApi/EsDailyLogsApi.csproj

# 2. 在另一個終端機執行測試腳本
./test_api.sh
實測支援完整 CRUD:成功將資料推入 Queue (202)、搜尋紀錄 (200)、更新/刪除指定的底層文件 (204)。
7. 維運避坑指南與最佳實踐
7.1 分片容量規劃(Shard Sizing)與配置方式
「單個 Shard 維持在 10 GB ~ 50 GB」是 Elasticsearch 官方的核心架構準則。ES 本身並沒有單一開關限制 Shard 容量,而是透過以下配置方式達成:
1. 時序資料(Logs / Metrics)👉 透過 ILM 自動控制(推薦)
在 ILM 策略中配置 max_primary_shard_size: "40gb",搭配 Index Template 設定 index.number_of_shards: 2:
ILM 自動 Rollover 策略設定:
PUT _ilm/policy/logs_ilm_policy
{
  "policy": {
    "phases": {
      "hot": {
        "actions": {
          "rollover": {
            "max_primary_shard_size": "40gb", // 當任一 Primary Shard 達 40GB 自動 Rollover
            "max_age": "1d"
          }
        }
      }
    }
  }
}
- 效果:每當資料累積約 80GB(2 Shards × 40GB)或滿 1 天時,ES 會自動切換至下一個新索引,由系統自動保證分片永遠落在最佳效能區間。
2. 靜態業務資料(商品、使用者資料庫)👉 透過預估容量配置
- 計算公式:
Primary Shards 數量 = 預估資料總量 / 30GB - 範例:預估總資料量 60GB,設定
number_of_shards: 2(單個 Shard 約 30GB)。
3. 記憶體(JVM Heap)與分片比率檢核
- 經驗法則:節點每 1 GB JVM Heap 承載的分片數量不應超過 20 個(例如:配置 31GB Heap 的節點,單節點分片總數建議小於 600 個),避免過度分片 (Over-sharding) 耗盡記憶體。
7.2 官方參考文件連結(Official References)
| 規範主題 | 官方文件說明 | 官方參考連結 |
|---|---|---|
| 分片容量規劃 | Size your shards (How many shards should I have?) | Elastic Docs: Size your shards |
| 避免過度分片 | Avoid oversharding (Capacity planning & Heap usage) | Elastic Docs: Avoid oversharding |
| ILM Rollover 動作 | Index Lifecycle Management: Rollover action | Elastic Docs: ILM Rollover |
| Data Streams 概念 | Set up a data stream & Backing indices | Elastic Docs: Data streams |
7.3 其他核心維運避坑點
- Client / Server 版本相容性:若 Elasticsearch Server 為
8.17.x,NuGet 請務必鎖定Elastic.Clients.Elasticsearch8.17.0;若安裝9.x會因compatible-with=9標頭造成 Server 拒絕請求(400 Bad Request)。 - 高吞吐寫入 Refresh Interval:預設
1s頻繁建立 Segment 會損耗 CPU,海量寫入建議調整為10s或30s。 - Data Stream 下的 Update / Delete:Data Stream 本質為 Append-only;若有稽核修正或個資去識別化需求,需取得底層 Backing Index 名稱(如
.ds-logs-app-prod-2026.08.23-000001)與_id進行操作。 - 備份與快照(Snapshot):Replica 僅提供節點容錯與查詢分流,無法防止人為誤刪操作;正式生產環境必須設定 SLM (Snapshot Lifecycle Management) 定時快照至外部雲端儲存(如 S3、GCS 或 NFS)。
心得
面對每日一億筆的海量時序資料:
- 寫入端:應用程式不再需要費心去算今天是什麼日期、組裝索引字串,直接丟給固定的 Data Stream 端點即可。
- 分片與生命週期:透過 ILM 自動依 Shard 容量(如 40GB)切分與定時清理,徹底解決過度分片 (Over-sharding) 與磁碟爆滿的維運惡夢。
- 應用層吞吐:透過非阻塞佇列類別
LogQueue(實作ILogQueue介面,底層封裝System.Threading.Channels.Channel<LogEntry>)進行記憶體排隊緩衝(這一段在生產環境完全有機會換成外部的 Message Queue 如 Kafka 或 RabbitMQ,為了演示先採用 .NET 內建的 Queue),搭配背景服務類別LogBatchProcessor(繼承BackgroundService)定期批次呼叫BulkAsync寫入,確保 API 回應速度在 1ms 內,兼顧高吞吐與系統穩定性。
範例位置
完整代碼位置: https://github.com/yaochangyu/sample.dotblog/tree/master/ElasticSearch/Lab.ES.LargeLog
若有謬誤,煩請告知,新手發帖請多包涵

Microsoft MVP Award 2010~2017 C# 第四季
Microsoft MVP Award 2018~2025 .NET
